Diffusion Models
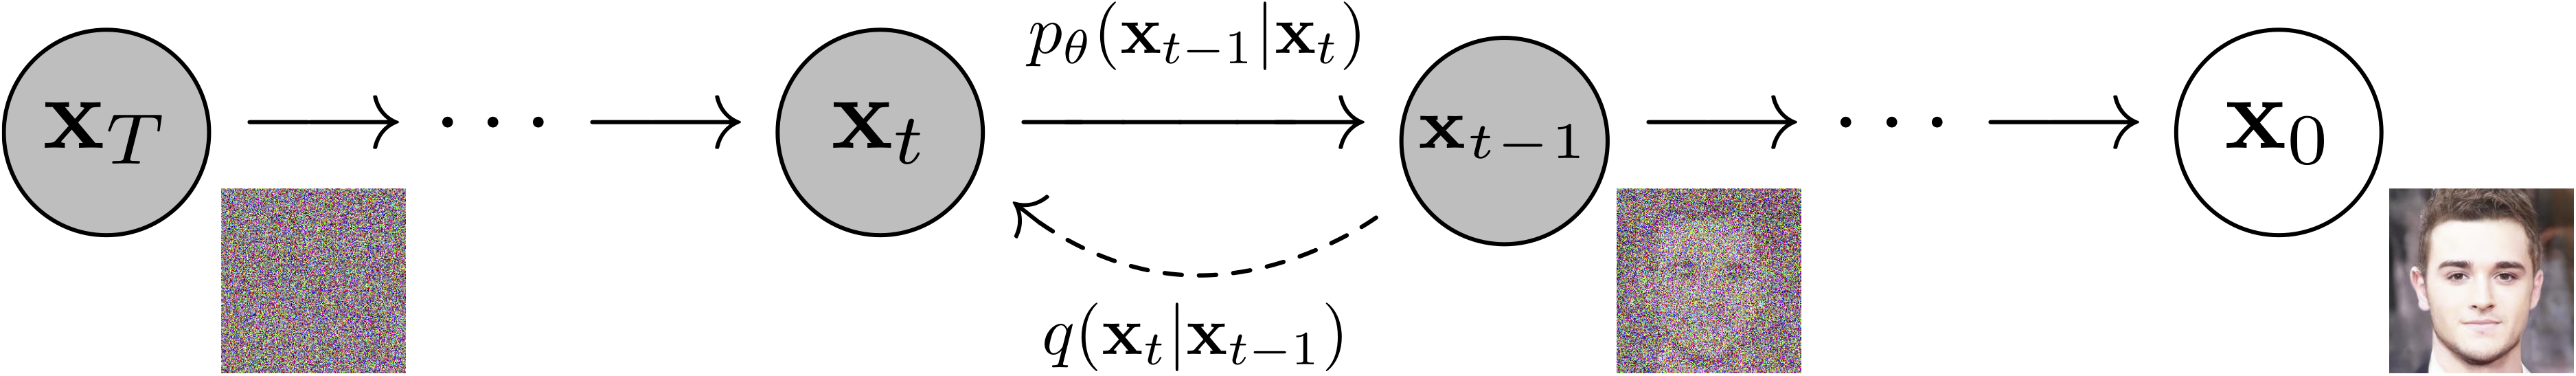
Getting a computer to draw an image that is not in its training set is hard because nobody knows how “plausible images” are spread across all possible pixel combinations. A denoising diffusion probabilistic model (DDPM) sidesteps the problem. It fixes a process that adds noise to an image step by step until only noise remains, then trains a network to undo that process by one small step. Generation starts from pure noise and undoes the process step by step until a new image is left.
 Open full-size image
Check the direction before reading the formulas: this picture places noisy xT on the left and clean x0 on the right. The solid arrows show learned denoising p; the dashed arrow q points back toward more noise. Training samples noisy states; generation follows the reverse transitions.
The Forward Process Fades the Image into Noise Step by Step
A variance schedule sets how much noise each step adds: is the variance of the noise added at step , and . The previous image is first scaled by , then Gaussian noise of variance is added:
Over many steps the scalings multiply. Let . Any timestep can be sampled directly from clean data:
In words: the image at step is the original scaled by , plus random noise scaled by .
Take a scalar example: , original , and sampled noise . The original is multiplied by and the noise by , giving . As grows, shrinks and the original fades; by the last step , is close to zero and almost only noise remains. Because training can jump straight to any , it never needs to simulate every earlier noising step.
The Network Learns to Guess the Noise in a Noisy Image
Generation needs the step in the other direction, from to . DDPM writes this step as a Gaussian whose mean and covariance come from the network:
One common parameterization does not have the network output the mean directly; it predicts the noise that was added to . A widely used simplified objective is
In words: draw a training image , a timestep , and noise ; build the noisy image with the forward formula; the network sees the noisy image and , guesses , and is penalized by the squared error.
Continue the example. Seeing , the network predicts noise , a squared noise error of . Putting the prediction back into the forward formula implies the original estimate . Predicting the actual sampled noise, , would recover in this arithmetic.
The network, however, sees only , not this draw of . with also gives . The same noisy image can come from many combinations of original and noise, and the squared error teaches the network the average of those possible noises: the conditional mean of the noise given .
Training samples data, a timestep (commonly uniformly from to ), and noise, then performs one denoiser evaluation and a gradient update. The noise target and denoiser output have the same shape as , and timestep conditioning tells the network which noise level it must handle.
Sampling Starts from Pure Noise and Removes Part of the Guessed Noise at Each Step
The network has learned one thing: look at a noisy image and guess the noise in it. Generation starts from pure noise; each step removes part of the noise the network guesses, then adds a little fresh noise. Because the network has learned regularities shared by a large collection of images rather than any single image, after all steps (the DDPM paper uses ) what remains is an image that resembles the training set without being in it.
For the discrete Gaussian DDPM in the original paper, Algorithms 1–2, take and . Sampling has three steps:
- Draw from . The schedule must make close to zero so the terminal distribution is approximately standard Gaussian; otherwise starting from is a mismatch that no number of steps repairs.
- For , compute the reverse mean from the network's noise prediction; for , draw fresh and compute ; at , return the mean without fresh noise.
- Return the final .
With an epsilon-predicting network, the reverse mean is
It says: subtract part of the predicted noise from the current image , then scale the result up by . One fixed choice for the variance of the fresh noise is .
Staying with the example, suppose this step has , so and . The network predicts noise for :
- The noise removed is , leaving .
- Scaling up gives , which is .
- The fresh noise has variance , a standard deviation of about .
So this step gives . Generation has no clean target; it repeats this with fixed weights, evaluating the denoiser again at each step. The exact forward posterior conditioned on both and is Gaussian; without known the true reverse conditional generally is not, and DDPM approximates it with a learned Gaussian transition.
Conditioning Tells the Denoiser What to Generate
Conditioning supplies additional information—such as a class, text representation, or measurement—to the denoiser. Guidance strengthens the effect of that condition. The widely used classifier-free guidance trains one network as both a conditional and an unconditional denoiser by replacing the condition with a null token at some probability during training. At sampling time it makes two noise predictions for the same image, with and without the condition, and amplifies their difference, so the result follows the condition more closely.
Design Choices Are Independent, and Evaluation Needs Several Measures
- The noise schedule, prediction target, model architecture, and sampler are separate design choices. “Predict noise with MSE” plus the reverse step above is one combination of them, not the complete definition of every diffusion model.
- Standard sampling is iterative and calls the model many times; faster samplers trade approximation for computation.
- Stronger guidance follows the condition more closely and also moves the trade-off between diversity and fidelity.
- A low denoising loss does not establish perceptual quality, diversity, or usefulness, and conditional generation can reproduce biases or memorized samples from the training data.
The canonical starting point is Denoising Diffusion Probabilistic Models.
Diffusion Explainer follows preset text prompts through Stable Diffusion’s text encoder, iterative denoising, and image decoder. Step through the process and compare prompts to locate where conditioning enters. It shows a latent-diffusion application, whereas the formulas in this note describe pixel-space DDPM; the autoencoder that compresses and restores images in latent diffusion is covered in Variational Autoencoders.