Grouping Data
groupby partitions rows by one or more keys, applies an operation to each
partition, and combines the results. Decide the desired output shape first.
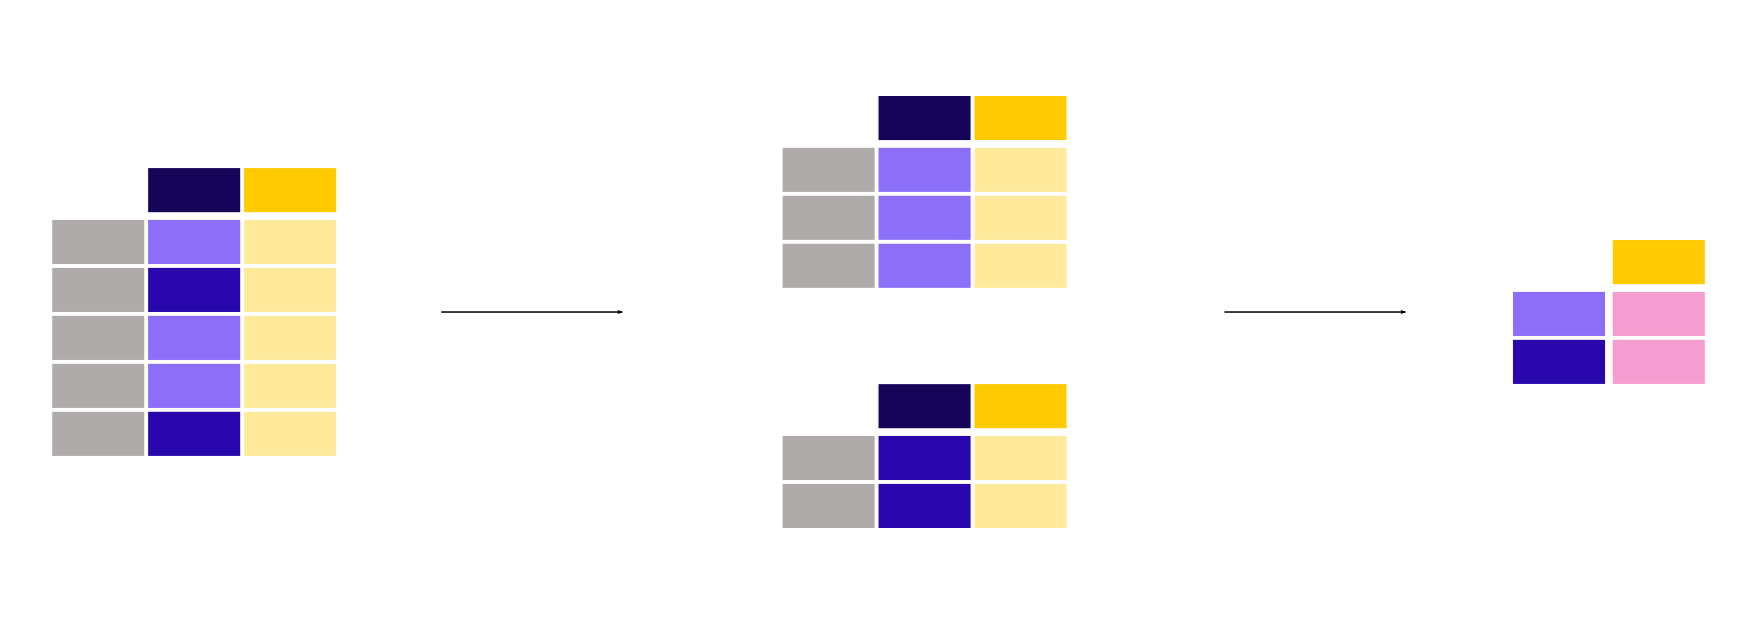 Open full-size image
Read from left to right: the grouping column separates rows into two groups, and the value column is summarized within each group. The final table has one row per group. This is the aggregation shape; transform instead returns values aligned to the original rows.
Choose by shape
import pandas as pd

sales = pd.DataFrame({
    "region": ["east", "east", "west", None], "product": ["A", "A", "B", "A"],
    "amount": [10.0, 30.0, 0.0, 5.0], "order_id": [1, 2, 3, 4],
})
summary = (
    sales.groupby(["region", "product"], as_index=False, dropna=False, observed=True)
         .agg(revenue=("amount", "sum"), orders=("order_id", "nunique"))
)

totals = sales.groupby("region", dropna=False, observed=True)["amount"].transform("sum")
sales["region_share"] = sales["amount"].div(totals.where(totals.ne(0)))
Named aggregation states both the source column and the output name. Built-in group operations are generally clearer and faster than Python callbacks.
Key decisions
dropna=Trueexcludes missing group keys by default; choose explicitly when missing is a meaningful group.observedaffects whether unused categories appear for categorical groupers; set it explicitly when output shape matters across versions.sort=Falsecan avoid unnecessary sorting when group order is irrelevant.as_index=Falsekeeps group keys as columns, often simplifying downstream use.
MultiIndex output
Grouping by several keys can produce a MultiIndex. Keep it when hierarchical
selection is useful; otherwise use as_index=False or reset_index() to return
to a flat table.
apply boundary
Use GroupBy.apply for genuinely group-shaped algorithms that cannot be expressed
as aggregation, transformation, filtering, windowing, or a join. Do not mutate
the group object inside the function, and test index behavior explicitly.
From group totals back to rows
Here summary has three rows: east/A gives revenue 40 and two distinct orders; west/B gives 0 and one order; the missing-region/A group gives 5 and one order. transform("sum") broadcasts the totals back as [40, 40, 0, 5], preserving the original row index. The shares become [0.25, 0.75, NaN, 1.0]; the zero-total group has no defined share.
In the grouping API, size counts rows, count counts non-missing values in each selected column, and nunique counts distinct non-missing values by default. They answer different questions. A group sum skips missing values and can return zero for an all-missing group; use sum(min_count=1) when that must remain unknown. filter(lambda g: len(g) >= 2) would keep both east rows rather than produce a summary row.