Querying DataFrames
A filter is an index-aligned boolean Series.
import pandas as pd

orders = pd.DataFrame({
    "customer_id": ["C1", "C2", None],
    "amount": [120, 80, 200],
    "status": ["paid", "shipped", "pending"],
    "created_at": pd.to_datetime(["2026-01-02", "2026-03-31 12:00", "2026-04-01"], format="mixed"),
})
mask = orders["amount"].ge(100) & orders["status"].isin(["paid", "shipped"])
large_orders = orders.loc[mask, ["customer_id", "amount", "status"]]
Predicate rules
- Parenthesize each comparison when combining with
&,|, or~. - Use
isinfor membership,betweenfor closed ranges, andisna/notnafor missingness. - Use
.str,.dt, and.cataccessors for typed string, datetime, and categorical operations. - Check the mask's index when it was built from another object; alignment can change the selected rows.
recent = orders.loc[
    orders["created_at"].ge("2026-01-01") & orders["created_at"].lt("2026-04-01")
]
missing_customer = orders.loc[orders["customer_id"].isna()]
query
DataFrame.query can make long analytical expressions readable:
threshold = 100
result = orders.query("amount >= @threshold and status == 'paid'")
Use ordinary boolean expressions when column names are awkward, predicates are constructed dynamically, or normal Python debugging is more valuable than the compact syntax. Never treat a query string assembled from untrusted input as a security boundary.
Filter versus select
Filtering chooses rows by a predicate. .loc can simultaneously choose rows and
columns; .iloc chooses by positions. Keeping those ideas separate prevents
many shape and label mistakes.
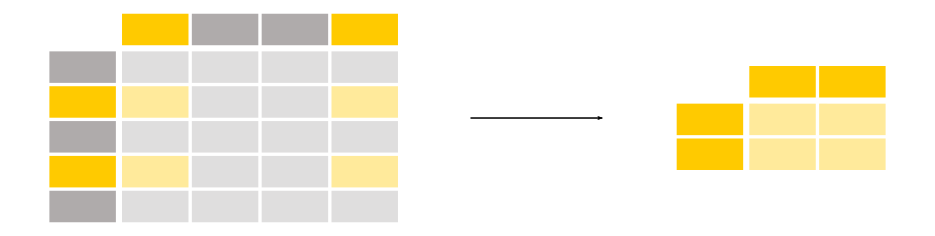 Open full-size image
First identify the selected rows at the left edge, then the selected columns along the top. Only their intersections appear in the result. In the opening example, mask makes the row decision and the list after the comma chooses the three output columns; neither step changes the values in those cells.
Check the selected rows
Here large_orders has shape (1, 3) and retains row 0; result also retains row 0 but keeps all four columns. recent retains rows 0 and 1. The half-open date interval includes all of March 31, whereas an upper timestamp of "2026-03-31" means midnight and excludes that afternoon.
In boolean indexing, nullable-boolean missing entries are treated as false. Use mask.fillna(True) only if unknown predicates should be retained. Python and/or cannot combine Series elementwise; &/| do. Despite its name, DataFrame.filter selects axis labels, not rows by their cell values. query can execute arbitrary code: never pass untrusted expressions to it.